ChatGPT / OpenAIGPT5.5 Performance Degradation
All impacted services have now fully recovered.
Resolved
Outages and recoveries from the services you depend on.
40 incidents
All impacted services have now fully recovered.
Resolved
This incident has been resolved.
Resolved
Between 14:18–17:20 UTC May 16th, we saw elevated error rates and response times with MobilePay requests. This is now resolved.
Resolved
We determined the issue was caused by a role used by the automation service losing required permissions following a configuration change. The issue was reported on May 15 at approximately 1:00 PM PT and resolved on May 16 at 11:50 AM PT. To help prevent similar incidents, we have improved our alerting and added audit logging for role and permission changes.
Resolved
This incident has been resolved.
Resolved
The issue has been resolved and error rates are back to normal.
Resolved
Between 02:59–04:58 UTC May 16th, we saw elevated error rates and response times with Apple Pay requests. This is now resolved.
Resolved
This incident has been resolved and we've re-enabled account registrations
Resolved
This incident has been resolved and Azure metrics are reporting as expected.
Resolved
This incident has been resolved and Azure metrics are reporting as expected.
Resolved
All queued events have been processed and data ingestion is operating normally. No data was lost during this incident.
Resolved
This incident has been resolved.
Resolved
On May 15, 2026, from approximately 07:43 UTC to 08:48 UTC, GitHub Actions experienced a degradation that caused workflow runs to fail or experience delayed starts for a subset of customers. The incident was triggered by a planned failover of supporting infrastructure used by GitHub Actions. During that operation, an automated service discovery update did not propagate correctly, which caused traffic to be routed incorrectly and increased request timeouts in a core dependency for workflow orchestration. <br /><br />At peak impact, 42% of Actions runs failed. Downstream services that depend on Actions workflow execution were also impacted, including GitHub Pages and Copilot cloud services. At 08:12 UTC, responders manually corrected the service discovery routing issue. Timeout and failure rates recovered shortly after, and we continued monitoring until full stabilization was confirmed across all affected services. The incident was marked resolved at 08:48 UTC. <br /><br />To prevent recurrence, we are implementing failover guardrails that validate service discovery state before completing failover operations, strengthening pre-flight and post-flight verification checks, and improving dependency resilience to reduce timeout cascades during infrastructure events.
Resolved
We have resolved the underlying cause of the kafka service disruption. Should any further issues be encountered, please reach out to support via the Aiven console. We apologise for the inconvenience caused by this issue, and commit to analysing and improving our platform to avoid future incidents similar to this one.
Resolved
Our apt repository should now be operating normally. If you continue to experience any problems, please open a ticket with our support team.
Resolved
This incident is fully resolved.
Resolved
This incident has been resolved.
Resolved
This morning, some third-party vendors received task reminder emails for tasks they had already been notified about. This was a one-time occurrence — we expect no additional emails to be sent as a result of this issue.
Resolved
All changes hav been applied.
Resolved
This incident has been resolved.
Resolved
The revert has been merged and deployed and we are seeing error rates return to normal and flows running. This issue has been resolved. More details at gitlab.com/gitlab-com/gl-infra/production/-/work_items/22135
Resolved
Search is now fully up to date for all users, and all issues with previous degraded functionality have been resolved.
Resolved
This issue has been resolved, fly ssh console invocations are now working correctly.
Resolved
This incident has been resolved.
Resolved
To ensure the best possible service for our customers amid the persistent issues in the AWS Middle East (UAE) region and following the cloud service provider’s advice to transition workloads to other regions, we have decided to remove this region from our available listings until further notice.
Resolved
We have taken measures to ensure continued stability. After continued monitoring, we have confirmed that error rates remain at normal levels for both the classic and new web apps.
Resolved
This incident has been resolved.
Resolved
On May 12th and 13th at various times, a subset of Upstash Redis instances on [Fly.io](http://Fly.io) experienced intermittent hangs and elevated error rates. The Redis process would stall inside a logging syscall — alive but not making progress — which made the issue hard to spot from our usual telemetry. After investigating with Fly's team, we identified the root cause as a bad interaction between a recent guest kernel update on Fly's newer machines and an upstream Cloud Hypervisor bug \([cloud-hypervisor#7672](https://github.com/cloud-hypervisor/cloud-hypervisor/issues/7672)\) affecting log writes from inside the VM. We mitigated by disabling the affected logging paths, and Fly has since rolled out a hypervisor-side patch, fully resolving the issue. No data was lost. Sorry for the disruption.
Resolved
On May 12th and 13th at various times, a subset of Upstash Redis instances on [Fly.io](http://Fly.io) experienced intermittent hangs and elevated error rates. The Redis process would stall inside a logging syscall — alive but not making progress — which made the issue hard to spot from our usual telemetry. After investigating with Fly's team, we identified the root cause as a bad interaction between a recent guest kernel update on Fly's newer machines and an upstream Cloud Hypervisor bug \([cloud-hypervisor#7672](https://github.com/cloud-hypervisor/cloud-hypervisor/issues/7672)\) affecting log writes from inside the VM. We mitigated by disabling the affected logging paths, and Fly has since rolled out a hypervisor-side patch, fully resolving the issue. No data was lost. Sorry for the disruption.
Resolved
Portal access has been restored.
Resolved
We can confirm that the issue is now resolved.
Resolved
The issue has been resolved. We will publish a public write-up on this status page once the investigation is completed.
Resolved
Processing of the backlog is complete.
Resolved
Starting around 04:00 UTC on May 14, 2026, Akamai identified an issue affecting Linode migration operations, including live, cold, and scheduled migrations. As a result, some customers experienced delays in migration processing, and customers undergoing certain migrations were temporarily unable to access their instances until processing resumed. The issue was caused by an unexpected restart of internal services required to process migrations. Following the restart, those services did not automatically recover as expected, which prevented migration tasks from initiating and led to a backlog of stalled operations. Akamai engineers restored the affected services, and migration processing resumed. Service was largely restored at approximately 03:15 UTC on May 15, 2026. Akamai is continuing to investigate the underlying cause of the unexpected service restart and is reviewing monitoring and recovery procedures to help prevent similar issues in the future. This summary reflects our current understanding of the incident based on available information. Our investigation is ongoing, and details may change as we learn more.
Resolved
Beginning at 02:49 UTC on May 15 2026 and lasting until 03:04 UTC, GitHub.com was unavailable for a subset of customers. This impact has been mitigated and normal service resumed. The issue was rooted in a sudden spike in traffic, with intermittent impact. We've identified the source of the traffic and prevented further disruption.
Resolved
This incident has been resolved, and service is operating normally again. Thanks for your patience.
Resolved
We've been monitoring Pinterest publishing and channel connections, and things have returned to normal. If you experience any further issues, please let us know. Thanks for your patience.
Resolved
This incident has been resolved.
Resolved
## Service Impact On May 7th between 08:14 and 09:25 UTC customers using [hosted agents](https://buildkite.com/docs/agent/buildkite-hosted), the [k8s stack](https://buildkite.com/docs/agent/self-hosted/agent-stack-k8s) and the Buildkite agent [acquire job feature](https://buildkite.com/docs/agent/cli/reference/start#run-a-single-job) experienced failures when starting a job, resulting in an error message `Missing agent. See: buildkite-agent bootstrap --help`. ## Incident Summary As part of our efforts to improve the performance of our platform we shipped a change to how database commits were grouped together. This change inadvertently caused certain job environment variables to be omitted when a job was assigned via the acquire method. These variables are key to our integration with hosted agents as well as customers using our Kubernetes stack and their omission caused any jobs launched via this method to fail. While we had test coverage that ensured these variables were populated, these tests did not exercise the code path used by acquire job effectively enough to indicate this problem before it was deployed. Furthermore, while parts of the change were placed behind a feature flag, the refactor of the code that caused this bug were not. Attempts to restore service by rolling back this change were hindered by the current revision being selected for deploy instead of the previous. The initial rollback was triggered at around 08:40 UTC, but it wasn’t until 09:05 we realised the mistake and began the rollback to the correct revision. The rollback started deploying at 09:16 and at 09:25 service was fully restored. 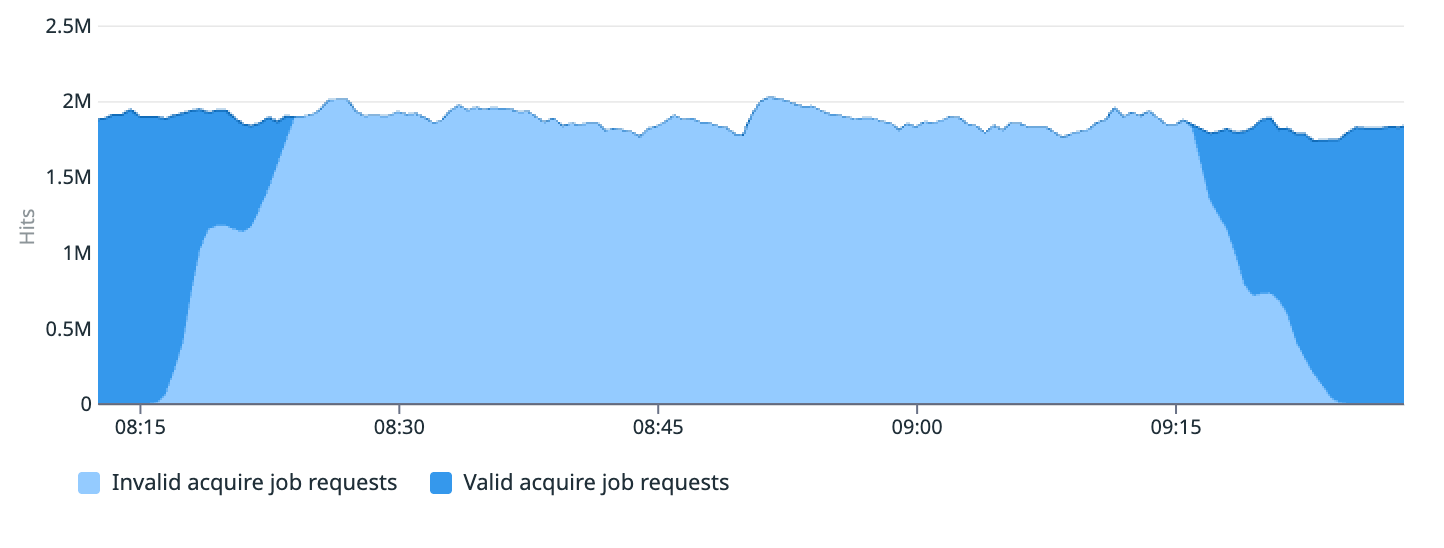 ## Changes we're making We have added additional rollback gates making it easier to identify when the incorrect revisions has been selected. Our test suite will be expanded to include contract tests for APIs used by Hosted Agent and the Kubernetes stack. Additionally, we are configuring Hosted Agent synthetic tests to automatically page on-call engineers when failures occur, improving our response times.
Resolved
As of the current time, our Engineering team has confirmed that the issue with Serverless Inference has been resolved. The root cause of the issue was an outage with our provider, Anthropic, which affected users of Sonnet 4.6 and Opus 4.7 models. According to Anthropic's status page (https://status.claude.com/incidents/8z7l5zcy0v3b), they have resolved the outage. If you continue to experience problems, please open a ticket with our Support team. We apologize for any inconvenience this may have caused.
Resolved